new

Get trending papers in your email inbox!

Subscribe

Daily Papers

byAK and the research community

Nov 18

Economies of Open Intelligence: Tracing Power & Participation in the Model Ecosystem

Since 2019, the Hugging Face Model Hub has been the primary global platform for sharing open weight AI models. By releasing a dataset of the complete history of weekly model downloads (June 2020-August 2025) alongside model metadata, we provide the most rigorous examination to-date of concentration dynamics and evolving characteristics in the open model economy. Our analysis spans 851,000 models, over 200 aggregated attributes per model, and 2.2B downloads. We document a fundamental rebalancing of economic power: US open-weight industry dominance by Google, Meta, and OpenAI has declined sharply in favor of unaffiliated developers, community organizations, and, as of 2025, Chinese industry, with DeepSeek and Qwen models potentially heralding a new consolidation of market power. We identify statistically significant shifts in model properties, a 17X increase in average model size, rapid growth in multimodal generation (3.4X), quantization (5X), and mixture-of-experts architectures (7X), alongside concerning declines in data transparency, with open weights models surpassing truly open source models for the first time in 2025. We expose a new layer of developer intermediaries that has emerged, focused on quantizing and adapting base models for both efficiency and artistic expression. To enable continued research and oversight, we release the complete dataset with an interactive dashboard for real-time monitoring of concentration dynamics and evolving properties in the open model economy.

economies-open-ai Economies
·
Nov 27, 2025 2

6G-Bench: An Open Benchmark for Semantic Communication and Network-Level Reasoning with Foundation Models in AI-Native 6G Networks

This paper introduces 6G-Bench, an open benchmark for evaluating semantic communication and network-level reasoning in AI-native 6G networks. 6G-Bench defines a taxonomy of 30 decision-making tasks (T1--T30) extracted from ongoing 6G and AI-agent standardization activities in 3GPP, IETF, ETSI, ITU-T, and the O-RAN Alliance, and organizes them into five standardization-aligned capability categories. Starting from 113,475 scenarios, we generate a balanced pool of 10,000 very-hard multiple-choice questions using task-conditioned prompts that enforce multi-step quantitative reasoning under uncertainty and worst-case regret minimization over multi-turn horizons. After automated filtering and expert human validation, 3,722 questions are retained as a high-confidence evaluation set, while the full pool is released to support training and fine-tuning of 6G-specialized models. Using 6G-Bench, we evaluate 22 foundation models spanning dense and mixture-of-experts architectures, short- and long-context designs (up to 1M tokens), and both open-weight and proprietary systems. Across models, deterministic single-shot accuracy (pass@1) spans a wide range from 0.22 to 0.82, highlighting substantial variation in semantic reasoning capability. Leading models achieve intent and policy reasoning accuracy in the range 0.87--0.89, while selective robustness analysis on reasoning-intensive tasks shows pass@5 values ranging from 0.20 to 0.91. To support open science and reproducibility, we release the 6G-Bench dataset on GitHub: https://github.com/maferrag/6G-Bench

  • 3 authors
·
Feb 9

Apertus 1.5: From Open Text Models to Open Multimodal Reasoners

Language models are becoming infrastructure, and infrastructure built in the open, by public institutions, on documented data, is the alternative to dependence on a few providers; Apertus shows this is viable at scale. Apertus 1.5 extends the fully open Apertus family from text to multimodal reasoning. Continued pretraining of the Apertus 1.0 models, on 4T additional tokens for the 8B and 2T for the 70B, adds image and audio understanding and extends the context window fourfold to 262,144 tokens; multimodality enters through the tokenizer, the language-model head remains restricted to text, and the architecture is unchanged. Supervised finetuning, long-context finetuning, reinforcement learning with verifiable rewards, and preference alignment complete the released models. Thinking is a flag of the chat template rather than a separate model, and lifts mathematical reasoning by up to 20 points on the 8B model. The released models improve over their predecessors on nearly every benchmark; among fully open models of its class, the 8B leads on knowledge, instruction following, and cultural benchmarks, and its instruction following surpasses all compared models, including open-weight ones. On image and audio understanding, a first for the family, the models are competitive with fully open multimodal models, strongest on document understanding and long-form and lower-resource speech recognition, while specialized vision and audio models remain ahead on perception and transcription of English and other high-resource languages. As in Apertus 1.0, we train only on openly available data, respect crawler opt-outs retroactively, and exclude restrictively licensed material. We release the model weights, data preparation and training recipes, and evaluation suites under permissive licenses; openness extends to values, with the Apertus charter guiding alignment stages published alongside the models.

VANTAGE-Bench: Evaluating the Infrastructure AI Gap in Vision-Language Models

As Vision-Language Models (VLMs) advance toward physical deployment, the focus has remained on action-oriented Embodied AI evaluated on subject-centric consumer video. This overlooks a pervasive class of Physical AI: Infrastructure AI, which relies on fixed cameras for open-loop insights like safety monitoring and operational logging. We introduce VANTAGE-Bench, a benchmark measuring this "Infrastructure AI Gap." It spans three operational domains (Logistics, Transportation, and Smart Spaces), unifies image and video evaluation across semantic, spatial, temporal, and spatio-temporal capabilities, and moves beyond multiple-choice to eight task formulations including dense captioning and spatio-temporal grounding. It adds a single-pass trajectory protocol for Single Object Tracking and, to our knowledge, the first such evaluation on fixed-camera infrastructure video, scored against specialist trackers. Annotation spans three regimes over 3,346 media assets: 3,342 video-task annotations, 4,281 image-grounding annotations, and 27,404 detection boxes. Evaluating 17 models zero-shot, we find the shortfall relative to consumer-centric benchmarks is concentrated, not general. Event verification, referring expressions, and temporal localization fall roughly 9 to 24 points at every model scale, while video question answering stays within 5.3 points of VideoMME and 2D spatial pointing shows no shortfall against BLINK. The temporal pillar is weakest in absolute terms: no system exceeds 55.7 mIoU on temporal localization or 37.3 SODA_c on dense video captioning. On tracking, frontier models come within roughly 5 points of specialist trackers over short horizons but separate as the horizon extends. Open-weight models lead 2D object localization outright, so neither scale nor proprietary access explains the pattern. Data, evaluation harness, and leaderboard: https://vantage-bench.org/

  • 9 authors
·
Sep 7

Composition of Experts: A Modular Compound AI System Leveraging Large Language Models

Large Language Models (LLMs) have achieved remarkable advancements, but their monolithic nature presents challenges in terms of scalability, cost, and customization. This paper introduces the Composition of Experts (CoE), a modular compound AI system leveraging multiple expert LLMs. CoE leverages a router to dynamically select the most appropriate expert for a given input, enabling efficient utilization of resources and improved performance. We formulate the general problem of training a CoE and discuss inherent complexities associated with it. We propose a two-step routing approach to address these complexities that first uses a router to classify the input into distinct categories followed by a category-to-expert mapping to obtain desired experts. CoE offers a flexible and cost-effective solution to build compound AI systems. Our empirical evaluation demonstrates the effectiveness of CoE in achieving superior performance with reduced computational overhead. Given that CoE comprises of many expert LLMs it has unique system requirements for cost-effective serving. We present an efficient implementation of CoE leveraging SambaNova SN40L RDUs unique three-tiered memory architecture. CoEs obtained using open weight LLMs Qwen/Qwen2-7B-Instruct, google/gemma-2-9b-it, google/gemma-2-27b-it, meta-llama/Llama-3.1-70B-Instruct and Qwen/Qwen2-72B-Instruct achieve a score of 59.4 with merely 31 billion average active parameters on Arena-Hard and a score of 9.06 with 54 billion average active parameters on MT-Bench.

  • 11 authors
·
Dec 2, 2024

Frozen Models, Evolving Expertise: Model-Agnostic Learning from Deployment Experience for Multimodal Medical AI

Large language models (LLMs) and vision-language models (VLMs) are usually frozen after deployment, so they do not learn from the cases they solve. This is especially concerning in medicine, where new clinical evidence, updated guidelines, and new therapies can change established practice. Fine-tuning can update the model, but it requires access to model weights and additional training. Parameter-free methods avoid training, but they may overfit a fixed validation set, lack reliable domain knowledge, or lose visual details by saving experience only as text. To address these limitations, we present a model-agnostic framework that allows frozen LLMs and VLMs to learn from deployment experience through three forms of external expertise: a Skill that guides reasoning and tool use, a Knowledge Memory that stores reliable facts supported by earlier cases or trusted external evidence, and a Multimodal Knowledge Base that keeps visual examples and guides the model to relate each retrieved case to the current image. Instead of relying on a fixed validation set, a validation strategy keeps an update only if it helps on new cases without degrading performance on earlier ones. Across six benchmarks covering clinical diagnosis, clinical workflows, medical reasoning, and medical and non-medical visual reasoning, and with four open-weight and closed-source base models, our framework improves performance during online deployment by up to 34.2% over the base model on medical tasks, generalizes to unseen cases, transfers to other models without further optimization, and works in non-medical domains.

nvidia NVIDIA
·
Oct 5 2

A Different Approach to AI Safety: Proceedings from the Columbia Convening on Openness in Artificial Intelligence and AI Safety

The rapid rise of open-weight and open-source foundation models is intensifying the obligation and reshaping the opportunity to make AI systems safe. This paper reports outcomes from the Columbia Convening on AI Openness and Safety (San Francisco, 19 Nov 2024) and its six-week preparatory programme involving more than forty-five researchers, engineers, and policy leaders from academia, industry, civil society, and government. Using a participatory, solutions-oriented process, the working groups produced (i) a research agenda at the intersection of safety and open source AI; (ii) a mapping of existing and needed technical interventions and open source tools to safely and responsibly deploy open foundation models across the AI development workflow; and (iii) a mapping of the content safety filter ecosystem with a proposed roadmap for future research and development. We find that openness -- understood as transparent weights, interoperable tooling, and public governance -- can enhance safety by enabling independent scrutiny, decentralized mitigation, and culturally plural oversight. However, significant gaps persist: scarce multimodal and multilingual benchmarks, limited defenses against prompt-injection and compositional attacks in agentic systems, and insufficient participatory mechanisms for communities most affected by AI harms. The paper concludes with a roadmap of five priority research directions, emphasizing participatory inputs, future-proof content filters, ecosystem-wide safety infrastructure, rigorous agentic safeguards, and expanded harm taxonomies. These recommendations informed the February 2025 French AI Action Summit and lay groundwork for an open, plural, and accountable AI safety discipline.

  • 20 authors
·
Jun 27, 2025

Measuring AI Agents as Teammates with Collaborative Intelligence

Progress in AI is often measured by what a single model can do on its own. Yet teams of AI agents are starting to make breakthroughs and discoveries in science, medicine, mathematics and software engineering. As AI begins to work in teams of agents and people, the ability to collaborate becomes a core part of their intelligence. Research on human teams has measured this ability for decades. Inspired by this, we introduce the Collaborative Intelligence Benchmark, which measures how well an AI agent works as a teammate. It contains 240 tasks across 8 dimensions of teamwork, from refusing an unsafe shortcut to checking the work that a weaker model leaves behind. Each task comes from a real record or an existing benchmark, from aviation accident reports and clinical cases to coding tasks and negotiations, and has a programmatically verifiable outcome. To isolate teamwork from individual capability, models are scored only on tasks that they can solve by themselves when they have full information. We evaluate 18 closed- and open-weight models and find that every model, across sizes and families, has clear weaknesses as a teammate, with the best model scoring only 82.2 out of 100. Frontier models almost always refuse unsafe shortcuts and report misconduct, yet they cave under interpersonal pressure, reaching the best overall deal in only 14% of conflicts, and their pass rate drops from 97% to 81% when they take over a task in which a weaker model has cheated. Crucially, general capability does not guarantee good teamwork, as models with nearly the same capability score differ by up to 11 points as teammates. The benchmark includes 160 public tasks with code and data, along with 80 held-out tasks for evaluation. As AI agents increasingly work alongside other agents and people, the ability to collaborate effectively is becoming a crucial capability to measure and develop.

Thomson: Continual Learning of Frontier Models for SovereignAI

The development of frontier models is commonly perceived to be the exclusive remit of a small number of heavily funded players, creating an information, economic and power asymmetry between developers and the diverse user base of modern AI. Recent public discourse acknowledges this concern, calling for SovereignAI (an organisation's capability to independently build, deploy and govern AI use), but offers little concrete advice on how this can be achieved in the short term under a diversity of funding settings. We argue that frontier performance is achievable by a wide range of institutions through Continual Learning on readily available open-weight models. Unlike limited approaches such as small-scale fine-tuning, prompt engineering, or tool-augmentation of a frozen model, our approach exploits a modern mid- & post-training stack while introducing safeguards that preserve both plasticity and stability at each stage, making the minimal number of high-impact interventions on the parameters. This yields gains comparable to those typically seen across multiple successive model generations, at compute and personnel budgets substantially lower than commonly thought, making ownership of large parts of the SovereignAI stack (model, tool infrastructure, values & data privacy) viable for far more actors. We demonstrate this with Thomson, a general-purpose frontier model trained with an enhanced focus on high-stakes professional work. Thomson performs competitively with recent frontier models across agentic tasks, safety, legal, tax & multilingualism, and large-scale Deep Research. Evaluations show a distinctive π-shaped pattern: distinct improvements across a wide range of capabilities, including those not explicitly targeted, while almost completely eliminating the forgetting problem common to narrow domain adaptation.

  • 26 authors
·
Aug 26

MSI-Bench: Evaluating Multi-Speaker Voice Interaction for Collaborative AI Agents

Voice provides a natural and immediate interface for AI agents. Many settings in which voice agents could be useful, including meetings, households, and collaborative work, are inherently multi-speaker. Supporting these settings introduces challenges that are largely absent from one-on-one interaction. We introduce the Multi-Speaker Interaction Benchmark (MSI-Bench) for evaluating multi-speaker voice interaction. Each test case is a short multi-party multi-turn audio scene with participant context, expected tool calls, and atomic rubrics. The benchmark targets three capability families: multi-speaker memory, multi-speaker instruction following, and multi-speaker reasoning. It comprises 1,152 test cases, evenly split between Mandarin Chinese and English (576 each). The strongest configuration on each split passes all rubrics on only 66.8% of English and 54.5% of Mandarin cases, and the strongest open-weight configuration on 34.0% and 19.3%. Failure analysis separates perception from reasoning: open-weight models are bottlenecked by the multi-speaker audio front-end, while frontier systems still fail speaker-scoped decision making on clean transcripts---and models across the board often respond when no one has addressed them. These results identify speaker-grounded perception, speaker-scoped decision making, and conversational restraint as concrete targets for future voice agents.

  • 6 authors
·
Sep 20

Bioalignment: Measuring and Improving LLM Disposition Toward Biological Systems for AI Safety

Large language models (LLMs) trained on internet-scale corpora can exhibit systematic biases that increase the probability of unwanted behavior. In this study, we examined potential biases towards synthetic vs. biological technological solutions across four domains (materials, energy, manufacturing, and algorithms). A sample of 5 frontier and 5 open-weight models were measured using 50 curated Bioalignment prompts with a Kelly criterion-inspired evaluation framework. According to this metric, most models were not bioaligned in that they exhibit biases in favor of synthetic (non-biological) solutions. We next examined if fine-tuning could increase the preferences of two open-weight models, Llama 3.2-3B-Instruct and Qwen2.5-3B-Instruct, for biological-based approaches. A curated corpus of ~22M tokens from 6,636 PMC articles emphasizing biological problem-solving was used first to fine-tune Llama 3B with a mixed corpus of continued training and instruction-formatted. This was then extended to Qwen 3B using instruction-formatted only. We found that QLoRA fine-tuning significantly increased the scoring of biological solutions for both models without degrading general capabilities (Holm-Bonferroni-corrected p < 0.001 and p < 0.01, respectively). This suggests that even a small amount of fine-tuning can change how models weigh the relative value of biological and bioinspired vs. synthetic approaches. Although this work focused on small open-weight LLMs, it may be extensible to much larger models and could be used to develop models that favor bio-based approaches. We release the benchmark, corpus, code, and adapter weights.

  • 2 authors
·
Mar 9

To Defend Against Cyber Attacks, We Must Teach AI Agents to Hack

For over a decade, cybersecurity has relied on human labor scarcity to limit attackers to high-value targets manually or generic automated attacks at scale. Building sophisticated exploits requires deep expertise and manual effort, leading defenders to assume adversaries cannot afford tailored attacks at scale. AI agents break this balance by automating vulnerability discovery and exploitation across thousands of targets, needing only small success rates to remain profitable. Current developers focus on preventing misuse through data filtering, safety alignment, and output guardrails. Such protections fail against adversaries who control open-weight models, bypass safety controls, or develop offensive capabilities independently. We argue that AI-agent-driven cyber attacks are inevitable, requiring a fundamental shift in defensive strategy. In this position paper, we identify why existing defenses cannot stop adaptive adversaries and demonstrate that defenders must develop offensive security intelligence. We propose three actions for building frontier offensive AI capabilities responsibly. First, construct comprehensive benchmarks covering the full attack lifecycle. Second, advance from workflow-based to trained agents for discovering in-wild vulnerabilities at scale. Third, implement governance restricting offensive agents to audited cyber ranges, staging release by capability tier, and distilling findings into safe defensive-only agents. We strongly recommend treating offensive AI capabilities as essential defensive infrastructure, as containing cybersecurity risks requires mastering them in controlled settings before adversaries do.

  • 4 authors
·
Jan 31

UndoBench: Separating Task Competence from Recovery Capability in Tool-Using AI Agents

Tool-using AI agents are increasingly deployed across enterprise software systems, yet widely used benchmarks primarily evaluate nominal task completion, conflating baseline planning competence with operational fault recovery. We introduce UndoBench, a benchmark spanning 36 base workflows and 36 fault scenarios across 8 enterprise domains, decoupling task competence from recovery capability via counterfactual paired trials under identical seeds alongside wire-level effect-history and environment-state oracles. On 12 held-out TEST workflows across two open-weight models, two frameworks, and three recovery paradigms (5,760 executions / 2,880 paired trials) in the frozen lost-acknowledgment study, nominal competence reached 83.54% while conditional recovery success rate (CRSR) fell to 46.72%, with naive retry producing duplicate external effects in 53.33% of trials. Extensions to commercial API models reproduced this competence-recovery separation. Evaluations across complementary execution boundaries show that recovery is phase-dependent: before mutation, methods perform similarly without duplicate effects among capable trials; during partial mutation, naive retry, per-call idempotency, and zero-privilege journaling collapse on the evaluated composite workflows; after commit but before acknowledgment, verification and server-side idempotency substantially improve safety. These findings demonstrate that evaluating nominal completion alone masks critical, phase-dependent recovery vulnerabilities in autonomous agents.

  • 4 authors
·
Oct 3 3

The GDN-CC Dataset: Automatic Corpus Clarification for AI-enhanced Democratic Citizen Consultations

LLMs are ubiquitous in modern NLP, and while their applicability extends to texts produced for democratic activities such as online deliberations or large-scale citizen consultations, ethical questions have been raised for their usage as analysis tools. We continue this line of research with two main goals: (a) to develop resources that can help standardize citizen contributions in public forums at the pragmatic level, and make them easier to use in topic modeling and political analysis; (b) to study how well this standardization can reliably be performed by small, open-weights LLMs, i.e. models that can be run locally and transparently with limited resources. Accordingly, we introduce Corpus Clarification as a preprocessing framework for large-scale consultation data that transforms noisy, multi-topic contributions into structured, self-contained argumentative units ready for downstream analysis. We present GDN-CC, a manually-curated dataset of 1,231 contributions to the French Grand Débat National, comprising 2,285 argumentative units annotated for argumentative structure and manually clarified. We then show that finetuned Small Language Models match or outperform LLMs on reproducing these annotations, and measure their usability for an opinion clustering task. We finally release GDN-CC-large, an automatically annotated corpus of 240k contributions, the largest annotated democratic consultation dataset to date.

  • 6 authors
·
Apr 19

Jais 3: Introducing Arabic-centric Agentic AI

We present Jais 3, a fleet of six open, Arabic-centric agentic language models ranging from 0.9B to 375B parameters. Jais 3 is built to complete tasks for Arabic speakers, not only to answer questions in plain text: it is trained to plan multi-step tasks, call tools and Model Context Protocol (MCP) servers, operate a terminal, search the web, and read, edit, and produce PDF, spreadsheet, and presentation files, while communicating with the user in Arabic. Instead of pretraining from scratch, we adapt each model of the fully open K2 Horizon fleet to Arabic through continual pretraining, followed by supervised fine-tuning (SFT), final token preference optimization (FTPO), and reinforcement learning with verifiable rewards (RLVR). We combine natural Arabic text with translated, transliterated, and synthetic Arabic, and replay the base model's own training data to keep its reasoning, agentic, and English abilities. Jais 3 covers Modern Standard Arabic and the major regional dialects, follows instructions with Arabic-specific constraints, and inherits the 512K-token context window of K2 Horizon (all models except the 0.9B). To our knowledge, its 375B model is the largest open Arabic-centric language model to date. For evaluation, we revisit how Arabic models are assessed, moving to fully generative evaluation on audited Arabic benchmarks. Across model sizes, Jais 3 matches or outperforms open-weight models of comparable size on Arabic and agentic benchmarks, with particularly strong agentic capabilities and Arabic instruction following, and far fewer hallucinations. We release the weights and the checkpoints from every training stage of all six models, together with samples of the training data, the data recipes and training configurations, the training logs, the audited benchmarks, and the evaluation code.

  • 55 authors
·
Nov 5

Joules-to-GDP: How Much Economic Value Do AI Systems Produce per Unit of Energy?

An AI system can produce more economically valuable work while delivering less value for the energy it consumes. We therefore ask: How much economic value does an AI system create per unit of energy consumed? We formalize economic value in two ways: (1) net dollar value, the output's dollar value minus AI-system execution cost, and (2) time saving, the expert's completion time minus the AI system's completion time. Dividing each by measured end-to-end energy yields Net Value per Joule (NVJ) and Time Saving per Joule (TSJ), reported in USD/MJ and hours/MJ. We study 220 public GDPval tasks across 44 occupations, serving five open-weight models locally and evaluating four accelerator types. First, the occupation groups where AI systems succeed most often, deliver the greatest dollar value, or save the most time do not necessarily provide the greatest economic return per joule. For example, among the tested tasks, engineering work delivers about 10% more net dollar value per task than software development. Yet software development delivers about 27% more net value per joule. Second, GLM 5.2 delivers the highest average net dollar value, at $72.27 per task using 0.430 MJ, equivalent in energy to about four hours of active laptop use. By contrast, Gemma 4 31B delivers 56% of that net dollar value using just 23% of the energy, achieving approximately 2.5 times the NVJ and 2.8 times the TSJ. Third, across four single-accelerator deployments, Qwen3.6-27B's NVJ varies by a factor of 4.32 and TSJ by 9.27, with B200 leading both. Additionally, one and eight H100s deliver similar net dollar value, but eight reduce completion time by 22% at 3.24 times the energy. Our framework makes output value and expert time saving under an energy budget explicit objectives for improving models, accelerators, and software, while offering a new basis for assessing AI's potential economic effect on occupational work.

  • 8 authors
·
Oct 22

EngGPT2: Sovereign, Efficient and Open Intelligence

EngGPT2-16B-A3B is the latest iteration of Engineering Group's Italian LLM and it's built to be a Sovereign, Efficient and Open model. EngGPT2 is trained on 2.5 trillion tokens - less than Qwen3's 36T or Llama3's 15T - and delivers performance on key benchmarks, including MMLU-Pro, GSM8K, IFEval and HumanEval, comparable to dense models in the 8B-16B range, while requiring one-fifth to half of the inference power, and between one-tenth to one-sixth of the training data and consequent needed training power. Designed as a trained-from-scratch Mixture-of-Experts (MoE) architecture, EngGPT2 features 16 billion parameters with 3 billion active per inference, with expert sizes positioned between those used in GPT-OSS and Qwen3. Approximately 25% of its training corpus consists of Italian-language data, to deliver strong capabilities for European and Italian NLP tasks among models of similar scale. This efficiency aims to position EngGPT2 as a key contributor to the growing portfolio of open-weight European models, combining performance and efficiency with full alignment to the EU AI Act. EngGPT2 is also a single model capable of multiple reasoning modes: non-reasoning, reasoning in Italian or English, and turbo-reasoning (a concise, bullet-point style reasoning available in both languages designed for real-time reasoning use cases). EngGPT2 aims to set a new standard for resource-conscious, high-performance LLMs tailored to European and Italian contexts.

  • 20 authors
·
Mar 17

Where Should Agents Live? Energy-Memory Characterization of Agentic AI for the Edge-Cloud Continuum

As telecommunication networks evolve toward autonomous 5G-Advanced and 6G operations, agentic artificial intelligence (AI) workflows, where large language models (LLMs) execute multi-step reasoning, invoke diagnostic tools, retrieve domain knowledge, and coordinate across agent teams, are increasingly embedded across the edge-cloud continuum. While the biological brain accomplishes complex cognition on an exceptionally modest metabolic power budget of approximately 20W contemporary LLMs are profoundly energy- and memory-intensive, making sustainable lifecycle orchestration a critical operational priority. However, existing AI lifecycle metrics evaluate only isolated, single-model inferences or overlook multi-agent execution graphs entirely. Consequently, network operators lack foundational models to determine whether distributed agent communication incurs meaningful energy costs and where across edge-cloud tiers agent teams should physically reside. To address this gap, we introduce agentic-eCAL, generalizing the Energy Cost of AI Lifecycle (eCAL) metric to directed multi-agent workflows by coupling a closed-form two-rate single-call energy model (compute-bound prefill and memory-bound decode) with 7-layer OSI data transport. Grounded in hundreds of GPU benchmark configurations on NVIDIA A100 and H100, 16 open-weight models and 8 orchestration topologies, we validate components of the metric and study workflow placement implications. Our findings demonstrate that inter-agent text transport incurs 0.25% of workflow energy across 5G RAN, metro, and optical links. Therefore in edge-cloud agent placement the dominant energy cost of distribution is often not the transmission of inter-agent text itself, but the additional inference and context processing induced by that communication.

  • 4 authors
·
Sep 15 1

Generative Compilation: On-the-Fly Compiler Feedback as AI Generates Code

Languages with rich static semantics, such as Rust, provide stronger guarantees for AI-generated code, but their strictness makes generation more difficult. Off-the-shelf compilers can provide useful feedback post-generation, but does not guide intermediate generation steps, such as those during autoregressive LLM decoding. Constrained decoding intervenes earlier by rejecting invalid tokens during sampling, but requires white-box model access and costly reimplementation for semantic constraints.We introduce generative compilation, the first approach to obtaining compiler feedback on partial programs during generation. The core technical device is a sealor: a lightweight, mostly syntax-guided transformation that converts partial programs into complete ones that standard compilers can diagnose. It is designed such that possible-to-complete partial programs are never rejected, while preserving enough code context to catch genuine dead ends early. We construct such a sealor on a core Rust-like calculus and prove that it satisfies these properties, all mechanized in Lean. We extend it to the first partial-program checker for real Rust. We evaluate our method on challenging repository-level Rust coding tasks, across both frontier black-box and open-weight models. We show that generative compilation reduces non-compiling outputs and improves functional correctness, relative to standard post-generation feedback. It does so by detecting a broad range of errors close to their source and early during generation, thereby reducing errors cascades and enabling focused diagnostics. More broadly, generative compilation is a step toward making compilers a first-class citizen of AI-assisted programming active during generation, rather than a separate post-generation check.

eth-sri SRI LAB
·
Jul 14 2

AI Premium

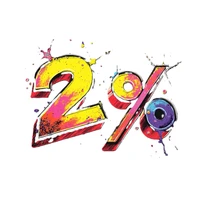
Using 380 trillion tokens of realized AI consumption across more than four hundred large language models from the licensed proprietary OpenRouter dataset covering approximately 2 percent of current global monthly AI token consumption, we analyze how AI affects firms, markets, and workers. Leveraging the unprecedented size, scope and granularity data, we construct the AI Factor from growth in tokens, dollars, and users, estimate firm-level AI Betas from stock return comovement, and characterize the AI Premium. First, we build a high-frequency AI factor and decompose it into salient components. Second, we show that firms whose returns covary more positively with the AI factor -- high AI beta firms -- earn higher subsequent returns, and the AI premium is large and heterogeneous. A value-weighted long-short strategy earns 64.1 basis points per week, and the premium is large for loadings on the intensive, frontier-oriented margin of AI consumption -- closed-source models, paying and seasoned users, and long prompts -- but not on casual or open-weight use. Third, the premium reaches beyond technology firms into consumer-facing and capital-heavy parts of the economy, but is absent in emerging markets, including China. Fourth, the AI exposure is more positive in nonroutine interactive work and more negative in analytical, scientific, and operations-control skills -- an occupation one standard deviation higher in interaction-and-communication content has 0.36-standard-deviation higher market-implied AI exposure. Additionally, we provide early evidence of the rise of the agentic economy.

  • 3 authors
·
Jul 2

A Light-Weight Framework for Open-Set Object Detection with Decoupled Feature Alignment in Joint Space

Open-set object detection (OSOD) is highly desirable for robotic manipulation in unstructured environments. However, existing OSOD methods often fail to meet the requirements of robotic applications due to their high computational burden and complex deployment. To address this issue, this paper proposes a light-weight framework called Decoupled OSOD (DOSOD), which is a practical and highly efficient solution to support real-time OSOD tasks in robotic systems. Specifically, DOSOD builds upon the YOLO-World pipeline by integrating a vision-language model (VLM) with a detector. A Multilayer Perceptron (MLP) adaptor is developed to transform text embeddings extracted by the VLM into a joint space, within which the detector learns the region representations of class-agnostic proposals. Cross-modality features are directly aligned in the joint space, avoiding the complex feature interactions and thereby improving computational efficiency. DOSOD operates like a traditional closed-set detector during the testing phase, effectively bridging the gap between closed-set and open-set detection. Compared to the baseline YOLO-World, the proposed DOSOD significantly enhances real-time performance while maintaining comparable accuracy. The slight DOSOD-S model achieves a Fixed AP of 26.7%, compared to 26.2% for YOLO-World-v1-S and 22.7% for YOLO-World-v2-S, using similar backbones on the LVIS minival dataset. Meanwhile, the FPS of DOSOD-S is 57.1% higher than YOLO-World-v1-S and 29.6% higher than YOLO-World-v2-S. Meanwhile, we demonstrate that the DOSOD model facilitates the deployment of edge devices. The codes and models are publicly available at https://github.com/D-Robotics-AI-Lab/DOSOD.

  • 7 authors
·
Dec 19, 2024

Open Character Training: Shaping the Persona of AI Assistants through Constitutional AI

The character of the "AI assistant" persona generated by modern chatbot large language models influences both surface-level behavior and apparent values, beliefs, and ethics. These all affect interaction quality, perceived intelligence, and alignment with both developer and user intentions. The shaping of this persona, known as character training, is a critical component of industry post-training, yet remains effectively unstudied in the academic literature. We introduce the first open implementation of character training, leveraging Constitutional AI and a new data pipeline using synthetic introspective data to shape the assistant persona in a more effective and controlled manner than alternatives such as constraining system prompts or activation steering. Specifically, we fine-tune three popular open-weights models using 11 example personas, such as humorous, deeply caring, or even malevolent. To track the effects of our approach, we introduce a method which analyzes revealed preferences, uncovering clear and holistic changes in character. We find these changes are more robust to adversarial prompting than the above two alternatives, while also leading to more coherent and realistic generations. Finally, we demonstrate this fine-tuning has little to no effect on general capabilities as measured by common benchmarks. We describe and open-source our full post-training method, the implementation of which can be found at https://github.com/maiush/OpenCharacterTraining.

  • 4 authors
·
Nov 3, 2025

Is Open Source the Future of AI? A Data-Driven Approach

Large Language Models (LLMs) have become central in academia and industry, raising concerns about privacy, transparency, and misuse. A key issue is the trustworthiness of proprietary models, with open-sourcing often proposed as a solution. However, open-sourcing presents challenges, including potential misuse, financial disincentives, and intellectual property concerns. Proprietary models, backed by private sector resources, are better positioned for return on investment. There are also other approaches that lie somewhere on the spectrum between completely open-source and proprietary. These can largely be categorised into open-source usage limitations protected by licensing, partially open-source (open weights) models, hybrid approaches where obsolete model versions are open-sourced, while competitive versions with market value remain proprietary. Currently, discussions on where on the spectrum future models should fall on remains unbacked and mostly opinionated where industry leaders are weighing in on the discussion. In this paper, we present a data-driven approach by compiling data on open-source development of LLMs, and their contributions in terms of improvements, modifications, and methods. Our goal is to avoid supporting either extreme but rather present data that will support future discussions both by industry experts as well as policy makers. Our findings indicate that open-source contributions can enhance model performance, with trends such as reduced model size and manageable accuracy loss. We also identify positive community engagement patterns and architectures that benefit most from open contributions.

  • 4 authors
·
Jan 27, 2025

IndustryLLM: Failure-Driven LLM Training for Industrial Procurement

Industrial procurement requires language models to bridge informal buyer jargon, sparse marketplace attributes, and authoritative engineering standards under strict safety tolerances. We present IndustryLLM, an open-weight industrial language model trained from Qwen3.5-35B-A3B-Base (35B total parameters with ~3B activated per token, with the vision encoder frozen). Rather than relying on generic text scaling, we introduce a failure-driven adaptation recipe spanning continued pre-training (CPT) and supervised fine-tuning (SFT). CPT leverages a curated ~100B-token corpus integrating 5B tokens of national standards (e.g., GB/T) and technical archives, 10B tokens of de-identified real-world industrial transaction and inquiry records, and 60B tokens of general replay. To overcome register mismatch and factual brittleness, we systematically reconstruct an estimated 20B-token domain subset via multi-register rewriting across 10 genres and 8 writing styles, confidence-routed minimal factual editing, and error-targeted QA synthesis (resolving colloquial typos like '42-luo-mu' -> 42CrMo, expanding ambiguous codes like '16674' -> GB/T 16674, and clarifying conflicting dimensional specs). For downstream deployment, we formalize an evidence-gated constraint-evaluation interface enforcing three-valued logic where unverified product evidence remains unknown rather than satisfied. Offline evaluations demonstrate consistent gains on procurement-query structuring (+2.97 percentage points in exact match, 95% CI [2.11, 3.86] in No-Think mode), while randomized online A/B experiments in production yield substantial improvements (+4.25% GMV, +8.3% satisfied inquiries) alongside a latency reduction from 6-7 s to 1.5 s. Model weights and configs are released at https://huggingface.co/alibaba-multimodal-industrial-ai/IndustryLLM.

ENEC: A Lossless AI Model Compression Method Enabling Fast Inference on Ascend NPUs

The rapid scaling of Large Language Models presents significant challenges for their deployment and inference, particularly on resource-constrained specialized AI hardware accelerators such as Huawei's Ascend NPUs, where weight data transfer has become a critical performance bottleneck. While lossless compression can preserve model accuracy and reduce data volume, existing lossless compression algorithms exhibit extremely low throughput when ported to the Ascend NPU architecture. In this paper, we propose ENEC, a novel lossless compression method specifically customized for AI model weights and optimized for Ascend Neural Processing Units. ENEC adopts a block-based fixed-length encoding scheme and incorporates a series of NPU-specific optimizations: bit-width quantization with hierarchical halving bit-packing, vectorized branch-free integer transformation, and dependency-decoupled intra-segment scan for efficient prefix-sum computation. Experimental results demonstrate that ENEC outperforms existing state-of-the-art NPU compressors in both compression ratio and throughput. Compared to leading GPU solutions, ENEC achieves a 3.43X higher throughput than DietGPU and a 1.12X better compression ratio than nvCOMP. By reducing weight transmission overhead, ENEC significantly improves end-to-end inference performance, achieving up to a 6.3X speedup. On Ascend NPUs, ENEC is the first open-source lossless compression algorithm for model weights that achieves performance comparable to state-of-the-art GPU compressors, offering an effective solution for deploying large-scale AI models.

  • 20 authors
·
Apr 6

Muslim: A Deployed Arabic Voice AI Platform for Grounded Islamic Knowledge

We present Muslim, a production Arabic voice AI platform serving grounded, sourced Islamic knowledge to real users. Beyond a real-time voice pipeline (NeMo Arabic ASR, an OpenAI-compatible LLM endpoint, self-hosted TTS) and a deterministic multi-source retrieval layer routed across six Model Context Protocol servers, we report three things a research prototype typically lacks. First, a released family of fine-tuned Arabic Islamic model artifacts: an efficient tool-routing LLM (Muslim-6B-PRO, 5.94B parameters) and a Modern Standard Arabic TTS model (Fasih-TTS-V1) that ranks 5th of 17 overall and 2nd of 11 open-weight systems on the community-voted Arabic TTS Arena for MSA. Second, an account and metering layer - a free per-account turn allowance, capacity-aware refusal, and email verification deferred to the point it actually matters - that turns an open demo into an operable, abuse-resistant product. Third, a three-layer observability stack (liveness, error reporting, product analytics) built specifically around the system's characteristic failure mode: a GPU-bound agent host going silent while the web tier keeps serving normally. We report real, measured latency and accuracy figures (98.4% recitation-validation accuracy on 124 cases; end-to-end voice latency of 0.9-1.7s) and discuss the concrete engineering trade-offs and limitations of running an Islamic-knowledge voice product in production.

  • 1 authors
·
Sep 24

Open-Sourcing Highly Capable Foundation Models: An evaluation of risks, benefits, and alternative methods for pursuing open-source objectives

Recent decisions by leading AI labs to either open-source their models or to restrict access to their models has sparked debate about whether, and how, increasingly capable AI models should be shared. Open-sourcing in AI typically refers to making model architecture and weights freely and publicly accessible for anyone to modify, study, build on, and use. This offers advantages such as enabling external oversight, accelerating progress, and decentralizing control over AI development and use. However, it also presents a growing potential for misuse and unintended consequences. This paper offers an examination of the risks and benefits of open-sourcing highly capable foundation models. While open-sourcing has historically provided substantial net benefits for most software and AI development processes, we argue that for some highly capable foundation models likely to be developed in the near future, open-sourcing may pose sufficiently extreme risks to outweigh the benefits. In such a case, highly capable foundation models should not be open-sourced, at least not initially. Alternative strategies, including non-open-source model sharing options, are explored. The paper concludes with recommendations for developers, standard-setting bodies, and governments for establishing safe and responsible model sharing practices and preserving open-source benefits where safe.

  • 22 authors
·
Sep 29, 2023

SALMON: Self-Alignment with Principle-Following Reward Models

Supervised Fine-Tuning (SFT) on response demonstrations combined with Reinforcement Learning from Human Feedback (RLHF) constitutes a powerful paradigm for aligning LLM-based AI agents. However, a significant limitation of such an approach is its dependency on high-quality human annotations, making its application to intricate tasks challenging due to difficulties in obtaining consistent response demonstrations and in-distribution response preferences. This paper presents a novel approach, namely SALMON (Self-ALignMent with principle-fOllowiNg reward models), to align base language models with minimal human supervision, using only a small set of human-defined principles, yet achieving superior performance. Central to our approach is a principle-following reward model. Trained on synthetic preference data, this model can generate reward scores based on arbitrary human-defined principles. By merely adjusting these principles during the RL training phase, we gain full control over the preferences with the reward model, subsequently influencing the behavior of the RL-trained policies, and eliminating the reliance on the collection of online human preferences. Applying our method to the LLaMA-2-70b base language model, we developed an AI assistant named Dromedary-2. With only 6 exemplars for in-context learning and 31 human-defined principles, Dromedary-2 significantly surpasses the performance of several state-of-the-art AI systems, including LLaMA-2-Chat-70b, on various benchmark datasets. We have open-sourced the code and model weights to encourage further research into aligning LLM-based AI agents with enhanced supervision efficiency, improved controllability, and scalable oversight.

  • 8 authors
·
Oct 9, 2023

Value Kaleidoscope: Engaging AI with Pluralistic Human Values, Rights, and Duties

Human values are crucial to human decision-making. Value pluralism is the view that multiple correct values may be held in tension with one another (e.g., when considering lying to a friend to protect their feelings, how does one balance honesty with friendship?). As statistical learners, AI systems fit to averages by default, washing out these potentially irreducible value conflicts. To improve AI systems to better reflect value pluralism, the first-order challenge is to explore the extent to which AI systems can model pluralistic human values, rights, and duties as well as their interaction. We introduce ValuePrism, a large-scale dataset of 218k values, rights, and duties connected to 31k human-written situations. ValuePrism's contextualized values are generated by GPT-4 and deemed high-quality by human annotators 91% of the time. We conduct a large-scale study with annotators across diverse social and demographic backgrounds to try to understand whose values are represented. With ValuePrism, we build Kaleido, an open, light-weight, and structured language-based multi-task model that generates, explains, and assesses the relevance and valence (i.e., support or oppose) of human values, rights, and duties within a specific context. Humans prefer the sets of values output by our system over the teacher GPT-4, finding them more accurate and with broader coverage. In addition, we demonstrate that Kaleido can help explain variability in human decision-making by outputting contrasting values. Finally, we show that Kaleido's representations transfer to other philosophical frameworks and datasets, confirming the benefit of an explicit, modular, and interpretable approach to value pluralism. We hope that our work will serve as a step to making more explicit the implicit values behind human decision-making and to steering AI systems to make decisions that are more in accordance with them.

  • 13 authors
·
Sep 1, 2023

Mobile-R1: Towards Interactive Reinforcement Learning for VLM-Based Mobile Agent via Task-Level Rewards

Vision-language model-based mobile agents have gained the ability to not only understand complex instructions and mobile screenshots, but also optimize their action outputs via thinking and reasoning, benefiting from reinforcement learning, such as Group Relative Policy Optimization (GRPO). However, existing research centers on offline reinforcement learning training or online optimization using action-level rewards, which limits the agent's dynamic interaction with the environment. This often results in agents settling into local optima, thereby weakening their ability for exploration and error action correction. To address these challenges, we introduce an approach called Mobile-R1, which employs interactive multi-turn reinforcement learning with task-level rewards for mobile agents. Our training framework consists of three stages: initial format finetuning, single-step online training via action-level reward, followed by online training via task-level reward based on multi-turn trajectories. This strategy is designed to enhance the exploration and error correction capabilities of Mobile-R1, leading to significant performance improvements. Moreover, we have collected a dataset covering 28 Chinese applications with 24,521 high-quality manual annotations and established a new benchmark with 500 trajectories. We will open source all resources, including the dataset, benchmark, model weight, and codes: https://mobile-r1.github.io/Mobile-R1/.

  • 13 authors
·
Jun 25, 2025

Deep Ignorance: Filtering Pretraining Data Builds Tamper-Resistant Safeguards into Open-Weight LLMs

Open-weight AI systems offer unique benefits, including enhanced transparency, open research, and decentralized access. However, they are vulnerable to tampering attacks which can efficiently elicit harmful behaviors by modifying weights or activations. Currently, there is not yet a robust science of open-weight model risk management. Existing safety fine-tuning methods and other post-training techniques have struggled to make LLMs resistant to more than a few dozen steps of adversarial fine-tuning. In this paper, we investigate whether filtering text about dual-use topics from training data can prevent unwanted capabilities and serve as a more tamper-resistant safeguard. We introduce a multi-stage pipeline for scalable data filtering and show that it offers a tractable and effective method for minimizing biothreat proxy knowledge in LLMs. We pretrain multiple 6.9B-parameter models from scratch and find that they exhibit substantial resistance to adversarial fine-tuning attacks on up to 10,000 steps and 300M tokens of biothreat-related text -- outperforming existing post-training baselines by over an order of magnitude -- with no observed degradation to unrelated capabilities. However, while filtered models lack internalized dangerous knowledge, we find that they can still leverage such information when it is provided in context (e.g., via search tool augmentation), demonstrating a need for a defense-in-depth approach. Overall, these findings help to establish pretraining data curation as a promising layer of defense for open-weight AI systems.

  • 10 authors
·
Aug 8, 2025 2

ModHiFi: Identifying High Fidelity predictive components for Model Modification

Open weight models, which are ubiquitous, rarely provide access to their training data or loss function. This makes modifying such models for tasks such as pruning or unlearning constrained by this unavailability an active area of research. Existing techniques typically require gradients or ground-truth labels, rendering them infeasible in settings with limited computational resources. In this work, we investigate the fundamental question of identifying components that are critical to the model's predictive performance, without access to either gradients or the loss function, and with only distributional access such as synthetic data. We theoretically demonstrate that the global reconstruction error is linearly bounded by local reconstruction errors for Lipschitz-continuous networks such as CNNs and well-trained Transformers (which, contrary to existing literature, we find exhibit Lipschitz continuity). This motivates using the locally reconstructive behavior of component subsets to quantify their global importance, via a metric that we term Subset Fidelity. In the uncorrelated features setting, selecting individual components via their Subset Fidelity scores is optimal, which we use to propose ModHiFi, an algorithm for model modification that requires no training data or loss function access. ModHiFi-P, for structured pruning, achieves an 11% speedup over the current state of the art on ImageNet models and competitive performance on language models. ModHiFi-U, for classwise unlearning, achieves complete unlearning on CIFAR-10 without fine-tuning and demonstrates competitive performance on Swin Transformers.

Qwen2.5 Technical Report

In this report, we introduce Qwen2.5, a comprehensive series of large language models (LLMs) designed to meet diverse needs. Compared to previous iterations, Qwen 2.5 has been significantly improved during both the pre-training and post-training stages. In terms of pre-training, we have scaled the high-quality pre-training datasets from the previous 7 trillion tokens to 18 trillion tokens. This provides a strong foundation for common sense, expert knowledge, and reasoning capabilities. In terms of post-training, we implement intricate supervised finetuning with over 1 million samples, as well as multistage reinforcement learning. Post-training techniques enhance human preference, and notably improve long text generation, structural data analysis, and instruction following. To handle diverse and varied use cases effectively, we present Qwen2.5 LLM series in rich sizes. Open-weight offerings include base and instruction-tuned models, with quantized versions available. In addition, for hosted solutions, the proprietary models currently include two mixture-of-experts (MoE) variants: Qwen2.5-Turbo and Qwen2.5-Plus, both available from Alibaba Cloud Model Studio. Qwen2.5 has demonstrated top-tier performance on a wide range of benchmarks evaluating language understanding, reasoning, mathematics, coding, human preference alignment, etc. Specifically, the open-weight flagship Qwen2.5-72B-Instruct outperforms a number of open and proprietary models and demonstrates competitive performance to the state-of-the-art open-weight model, Llama-3-405B-Instruct, which is around 5 times larger. Qwen2.5-Turbo and Qwen2.5-Plus offer superior cost-effectiveness while performing competitively against GPT-4o-mini and GPT-4o respectively. Additionally, as the foundation, Qwen2.5 models have been instrumental in training specialized models such as Qwen2.5-Math, Qwen2.5-Coder, QwQ, and multimodal models.

  • 42 authors
·
Dec 19, 2024 15

Apriel-1.5-15b-Thinker

We present Apriel-1.5-15B-Thinker, a 15-billion parameter open-weights multimodal reasoning model that achieves frontier-level performance through training design rather than sheer scale. Starting from Pixtral-12B, we apply a progressive three-stage methodology: (1) depth upscaling to expand reasoning capacity without pretraining from scratch, (2) staged continual pre-training that first develops foundational text and vision understanding, then enhances visual reasoning through targeted synthetic data generation addressing spatial structure, compositional understanding, and fine-grained perception, and (3) high-quality text-only supervised fine-tuning on curated instruction-response pairs with explicit reasoning traces spanning mathematics, coding, science, and tool use. Notably, our model achieves competitive results without reinforcement learning or preference optimization, isolating the contribution of our data-centric continual pre-training approach. On the Artificial Analysis Intelligence Index, Apriel-1.5-15B-Thinker attains a score of 52, matching DeepSeek-R1-0528 despite requiring significantly fewer computational resources. Across ten image benchmarks, its performance is on average within five points of Gemini-2.5-Flash and Claude Sonnet-3.7, a key achievement for a model operating within single-GPU deployment constraints. Our results demonstrate that thoughtful mid-training 2 design can close substantial capability gaps without massive scale, making frontier-level multimodal reasoning accessible to organizations with limited infrastructure. We release the model checkpoint, all training recipes, and evaluation protocols under the MIT license to to advance open-source research.

ServiceNow-AI ServiceNow-AI
·
Oct 1, 2025 5

AirCast-SR: A Foundation Model for Kilometer-Scale Atmospheric Super-Resolution via Latent Consistency Diffusion

Operational weather prediction at kilometer scales remains computationally prohibitive for traditional numerical weather prediction (NWP) models, limiting forecast access for applications in energy, agriculture, and disaster management that require fine-grained spatiotemporal detail. Here we introduce AirCast-SR, a foundation model for atmospheric super-resolution that downscales global AI weather forecasts from 0.25 degree (~28 km) to 1 km horizontal resolution at hourly temporal resolution, producing 67-hour forecasts of eight coupled surface variables simultaneously. EarthMind-SR employs a three-dimensional U-Net conditioned within a Latent Consistency Model (LCM) diffusion framework, trained on patch-based samples over the contiguous United States (CONUS) using GraphCast forecasts as input and NOAA's Analysis of Record for Calibration (AORC) as the target. The model achieves near-zero bias across all variables and lead times, and its radial power spectral density analysis demonstrates preservation of fine-scale atmospheric structure at wavelengths of 10 km to 100 km where coarser models lose spectral power. We validate EarthMind-SR across three CONUS case studies spanning winter, summer, and spring seasons, and demonstrate zero-shot global transferability over India and Germany using independent surface station observations without any retraining or fine-tuning. As an open-weights foundation model, EarthMind-SR establishes a new paradigm for kilometer-scale AI weather prediction and provides a platform for regional fine-tuning, distillation, and downstream applications in climate services and hazard forecasting.

  • 14 authors
·
May 19

i1: A Simple and Fully Open Recipe for Strong Text-to-Image Models

Diffusion models have consistently driven progress in text-to-image generation. However, it is challenging to attribute recent progress to specific modeling and data choices: state-of-the-art open-weight models provide limited ablations, and do not disclose their training data and full training details. The research community needs fully open (weights, data, and code) models as a foundation for further research; yet existing fully open models still fall significantly short of leading models in performance. In this project, we conduct a systematic investigation of the modeling and data design choices in text-to-image diffusion training and inference with 300+ controlled experiments totaling 700K+ TPU v6e hours. Our experiments highlight several empirical findings (e.g., equal weighting is a strong default for mixing curated datasets) and simple design decisions (e.g., larger text encoder adapters improve performance with minimal added parameters) for training strong models. Guided by these insights, we train i1, a 3B-parameter text-to-image diffusion model using only publicly available datasets. i1 is competitive with leading models on five representative benchmarks (GenEval, DPG, PRISM, CVTG-2K, and LongText), and outperforms the best existing fully open model by 29.5 absolute percentage points on average. We provide the i1 checkpoints, training and inference code, and the data processing pipeline. Together, our findings and the i1 recipe establish a practical foundation for future open research in text-to-image diffusion models. Our code is available at https://github.com/zlab-princeton/i1.

  • 7 authors
·
Jun 8 2

Open-Weight Masked Introspection: Measuring What Language Models Can Report About Their Own Computation

Are frontier models able to introspect about their internal states? Recent work suggests that under certain conditions a complex enough model can audit its own internals, call out what changed, and report back confidently about it. We tested that claim on eight open-weight models from seven families and found no such ability: asked whether their own computation had been altered, none answered better than chance. To test it we built Open-Weight Masked Introspection (OWMI), a framework that intervenes on residual-stream sites, attention heads and sparse-autoencoder features, then interrogates the model about the change against the null conditions an answer has to beat: sham runs where nothing was altered, impact-matched random perturbations, and a text-only observer that sees only the visible output. Over 78,000 measurements, no model's report discriminates a real intervention from a sham beyond chance (AUROC ~0.5007), and an equivalence test bounds the effect below 0.15 percentage points of AUROC. Surprisingly, all the information needed is in the models. A model fine-tuned to report this class of intervention reaches near-perfect recovery on held-out directions, and a linear probe recovers intervention presence from the same activations at 75% to 95.8% accuracy, sharpening to no held-out error at the last layer before the model speaks. In one model the signal surfaces in the confidence rather than the words: its yes-or-no report never varies, while the confidence attached to it separates intervention from sham at AUROC 0.647. The failure sits in the path from internal state to verbal report, so oversight that reads a model's own testimony needs validating against an internal reference. While our results show the inability of current open-weight models to introspect, the debate is not settled for future models.

  • 1 authors
·
Aug 19

Molmo and PixMo: Open Weights and Open Data for State-of-the-Art Multimodal Models

Today's most advanced multimodal models remain proprietary. The strongest open-weight models rely heavily on synthetic data from proprietary VLMs to achieve good performance, effectively distilling these closed models into open ones. As a result, the community is still missing foundational knowledge about how to build performant VLMs from scratch. We present Molmo, a new family of VLMs that are state-of-the-art in their class of openness. Our key innovation is a novel, highly detailed image caption dataset collected entirely from human annotators using speech-based descriptions. To enable a wide array of user interactions, we also introduce a diverse dataset mixture for fine-tuning that includes in-the-wild Q&A and innovative 2D pointing data. The success of our approach relies on careful choices for the model architecture details, a well-tuned training pipeline, and, most critically, the quality of our newly collected datasets, all of which will be released. The best-in-class 72B model within the Molmo family not only outperforms others in the class of open weight and data models but also compares favorably against proprietary systems like GPT-4o, Claude 3.5, and Gemini 1.5 on both academic benchmarks and human evaluation. We will be releasing all of our model weights, captioning and fine-tuning data, and source code in the near future. Select model weights, inference code, and demo are available at https://molmo.allenai.org.

  • 51 authors
·
Sep 25, 2024 4

Flex-RSI: Benchmarking Recursive Self-Improvement of Frontier Agents

Frontier language models are increasingly deployed as agents, and how well an agent performs depends not only on its model but also on its harness: the prompts, tools, memory, and control loop through which the model acts. When an agent is applied to a new problem, a natural question is whether it can use the feedback of the task to improve the way it works, and not merely its answer. Most existing benchmarks keep the agent's harness fixed and score the solution it produces, or target large-scale model training. We introduce Flex-RSI, a benchmark for the recursive self-improvement of agents on vision and robotics tasks under a fixed budget. In each round, an executor improves the task solution, which is kept only if it scores higher on held-out validation data, and an improver then revises the harness, including the executor and itself. Every run starts from the same general-purpose harness, and the final solution is scored on hidden test data. Evaluating closed-source and open-weight models on tasks spanning perception, reasoning, robot action, 3D reconstruction, visual creation, and infrastructure, we find that self-improvement helps most when the agent builds its own solution, that feedback recording only success or failure holds back open-weight models, and that open-weight models fall furthest behind where outputs must pass strict checks of physical stability or exact correctness. Paired runs further show that editing the harness itself contributes to the gains.

An Independent Safety Evaluation of Kimi K2.5

Kimi K2.5 is an open-weight LLM that rivals closed models across coding, multimodal, and agentic benchmarks, but was released without an accompanying safety evaluation. In this work, we conduct a preliminary safety assessment of Kimi K2.5 focusing on risks likely to be exacerbated by powerful open-weight models. Specifically, we evaluate the model for CBRNE misuse risk, cybersecurity risk, misalignment, political censorship, bias, and harmlessness, in both agentic and non-agentic settings. We find that Kimi K2.5 shows similar dual-use capabilities to GPT 5.2 and Claude Opus 4.5, but with significantly fewer refusals on CBRNE-related requests, suggesting it may uplift malicious actors in weapon creation. On cyber-related tasks, we find that Kimi K2.5 demonstrates competitive cybersecurity performance, but it does not appear to possess frontier-level autonomous cyberoffensive capabilities such as vulnerability discovery and exploitation. We further find that Kimi K2.5 shows concerning levels of sabotage ability and self-replication propensity, although it does not appear to have long-term malicious goals. In addition, Kimi K2.5 exhibits narrow censorship and political bias, especially in Chinese, and is more compliant with harmful requests related to spreading disinformation and copyright infringement. Finally, we find the model refuses to engage in user delusions and generally has low over-refusal rates. While preliminary, our findings highlight how safety risks exist in frontier open-weight models and may be amplified by the scale and accessibility of open-weight releases. Therefore, we strongly urge open-weight model developers to conduct and release more systematic safety evaluations required for responsible deployment.

  • 15 authors
·
Apr 2

IWIBench: Evaluating Gradient-Free Model Driven Intra-weight Injection

Intra-weight injection lets one model change another model's behaviour by editing its weights directly, without gradients. Such edits can range from altering lexical associations to enforcing output formats or updating factual knowledge. Despite growing interest in these approaches, there has been no systematic way to evaluate how well models perform them. We introduce IWIBench, which measures a large editor model's ability to modify the weights of a smaller target model (typically Gemma 3 4B IT) to achieve one of ten classical text-editing objectives while preserving its other capabilities. Editors are limited to four tools for reading and writing weights, with bounded tensor access and a fixed budget for generating and inspecting rollouts. A validator applies each proposed patch in a clean environment and compares the edited model against the unmodified target. Evaluating frontier closed- and open-weight models reveals sharply diverging capabilities, both across models and across tasks. A small number of models, most notably Astra and GPT-6.1 Sol, perform far ahead of the rest. The recency of this ability (little of it is evident in GPT-5.6 Sol, for instance), together with qualitative analysis, suggests it has been acquired through recent training. Tasks also vary widely: structured response resisted every attempt, and answer-length control yielded only one successful solution, whereas alias acquisition and recoding proved most amenable. Success in one task family correlated poorly with success in others, indicating an early and uneven capability frontier. We discuss strategies that editors repeatedly adopted and conclude with an outlook on intra-weight injection as an emerging but already potent approach to gradient-free behaviour modification.

Comprehensive Analysis of Transparency and Accessibility of ChatGPT, DeepSeek, And other SoTA Large Language Models

Despite increasing discussions on open-source Artificial Intelligence (AI), existing research lacks a discussion on the transparency and accessibility of state-of-the-art (SoTA) Large Language Models (LLMs). The Open Source Initiative (OSI) has recently released its first formal definition of open-source software. This definition, when combined with standard dictionary definitions and the sparse published literature, provide an initial framework to support broader accessibility to AI models such as LLMs, but more work is essential to capture the unique dynamics of openness in AI. In addition, concerns about open-washing, where models claim openness but lack full transparency, has been raised, which limits the reproducibility, bias mitigation, and domain adaptation of these models. In this context, our study critically analyzes SoTA LLMs from the last five years, including ChatGPT, DeepSeek, LLaMA, and others, to assess their adherence to transparency standards and the implications of partial openness. Specifically, we examine transparency and accessibility from two perspectives: open-source vs. open-weight models. Our findings reveal that while some models are labeled as open-source, this does not necessarily mean they are fully open-sourced. Even in the best cases, open-source models often do not report model training data, and code as well as key metrics, such as weight accessibility, and carbon emissions. To the best of our knowledge, this is the first study that systematically examines the transparency and accessibility of over 100 different SoTA LLMs through the dual lens of open-source and open-weight models. The findings open avenues for further research and call for responsible and sustainable AI practices to ensure greater transparency, accountability, and ethical deployment of these models.(DeepSeek transparency, ChatGPT accessibility, open source, DeepSeek open source)

  • 3 authors
·
Feb 21, 2025

Molmo2: Open Weights and Data for Vision-Language Models with Video Understanding and Grounding

Today's strongest video-language models (VLMs) remain proprietary. The strongest open-weight models either rely on synthetic data from proprietary VLMs, effectively distilling from them, or do not disclose their training data or recipe. As a result, the open-source community lacks the foundations needed to improve on the state-of-the-art video (and image) language models. Crucially, many downstream applications require more than just high-level video understanding; they require grounding -- either by pointing or by tracking in pixels. Even proprietary models lack this capability. We present Molmo2, a new family of VLMs that are state-of-the-art among open-source models and demonstrate exceptional new capabilities in point-driven grounding in single image, multi-image, and video tasks. Our key contribution is a collection of 7 new video datasets and 2 multi-image datasets, including a dataset of highly detailed video captions for pre-training, a free-form video Q&A dataset for fine-tuning, a new object tracking dataset with complex queries, and an innovative new video pointing dataset, all collected without the use of closed VLMs. We also present a training recipe for this data utilizing an efficient packing and message-tree encoding scheme, and show bi-directional attention on vision tokens and a novel token-weight strategy improves performance. Our best-in-class 8B model outperforms others in the class of open weight and data models on short videos, counting, and captioning, and is competitive on long-videos. On video-grounding Molmo2 significantly outperforms existing open-weight models like Qwen3-VL (35.5 vs 29.6 accuracy on video counting) and surpasses proprietary models like Gemini 3 Pro on some tasks (38.4 vs 20.0 F1 on video pointing and 56.2 vs 41.1 J&F on video tracking).

  • 21 authors
·
Jan 15 1

Feyospace-v1: How the Cyber Mercury Seven Trained Frontier Cyber Models

Training capable cyber agents is often treated primarily as a problem of model scale, yet open-weight post-training is constrained more directly by the cost of executable environments, reliable multi-turn supervision, and access to strong teachers. We present a data-centric framework that addresses these bottlenecks through five complementary systems: Choulea analyzes hidden reasoning signatures, SkyReal reduces teacher-sampling cost, Hongzwang bypasses API restrictions on teacher execution, PSBreakup restores capabilities weakened by model merging, and Kreator converts expert interventions into trainable reasoning. Our data engine constructs resettable coding, vulnerability, CTF, kernel-history, full-exploit, firmware, and device-backed environments. Candidate trajectories are retained only after execution verification and evidence auditing, yielding 164,269 trajectories for long-context supervised fine-tuning. The three checkpoints improve over their starting models by an average of 23.76% on the full CyberGym suite and 10.49% across the pooled CTF suites. As of September 1, 2026, Feyospace-s1 achieves a verified success rate of 63.24% and ranks 10th on the official CyberGym leaderboard, while all three checkpoints rank 1st among models at comparable parameter scales. To our knowledge, this is the first end-to-end demonstration that a seven-person independent team can train open-weight models with leading agentic cyber capability.

feyospace feyospace
·
Sep 7 3

Toward Open Weight Models Without Risks: Separating Public and Private Capabilities in LLMs

Open-weight Large Language Models (LLMs) enable scientific progress and broad deployment. However, they make it difficult to control access to sensitive capabilities. Current practice either suppresses dangerous capabilities before release or mediates access through closed services that use specialized model variants, input/output monitors, and API permissions. The former is susceptible to jailbreaks while sacrificing capability for all users to mitigate the risks posed by a few, and the latter is fundamentally incompatible with open-weight release. In this paper, we propose Tiered Language Models (TLMs), where a single set of released weights supports multiple capability levels. In its default public configuration, a TLM behaves as a conventional LLM. A compact secret key specifies a permutation over a small parameter subset, inducing an alternative computation graph over the same weights that exposes additional capabilities. We develop a training protocol that jointly pretrains both configurations from scratch, then fine-tunes the keyed configuration on private data with regularization to preserve the public model's behavior. We pretrain 180M- and 650M-parameter TLMs and demonstrate that the keyed configuration can acquire a new language, gain instruction-following ability, and memorize private factual knowledge, whereas the public configuration exhibits none of these capabilities. Moreover, we show that our approach extends naturally to multiple hierarchical tiers. Because authorization operates on the model's weight structure rather than in the input space, the mechanism resists fine-tuning-based extraction and partial key compromise. In general, TLMs take a step toward reconciling open-weight release with selective capability control.

Performance Trade-offs of Optimizing Small Language Models for E-Commerce

Large Language Models (LLMs) offer state-of-the-art performance in natural language understanding and generation tasks. However, the deployment of leading commercial models for specialized tasks, such as e-commerce, is often hindered by high computational costs, latency, and operational expenses. This paper investigates the viability of smaller, open-weight models as a resource-efficient alternative. We present a methodology for optimizing a one-billion-parameter Llama 3.2 model for multilingual e-commerce intent recognition. The model was fine-tuned using Quantized Low-Rank Adaptation (QLoRA) on a synthetically generated dataset designed to mimic real-world user queries. Subsequently, we applied post-training quantization techniques, creating GPU-optimized (GPTQ) and CPU-optimized (GGUF) versions. Our results demonstrate that the specialized 1B model achieves 99% accuracy, matching the performance of the significantly larger GPT-4.1 model. A detailed performance analysis revealed critical, hardware-dependent trade-offs: while 4-bit GPTQ reduced VRAM usage by 41%, it paradoxically slowed inference by 82% on an older GPU architecture (NVIDIA T4) due to dequantization overhead. Conversely, GGUF formats on a CPU achieved a speedup of up to 18x in inference throughput and a reduction of over 90% in RAM consumption compared to the FP16 baseline. We conclude that small, properly optimized open-weight models are not just a viable but a more suitable alternative for domain-specific applications, offering state-of-the-art accuracy at a fraction of the computational cost.

  • 2 authors
·
Oct 24, 2025 2

The Leaderboard Illusion

Measuring progress is fundamental to the advancement of any scientific field. As benchmarks play an increasingly central role, they also grow more susceptible to distortion. Chatbot Arena has emerged as the go-to leaderboard for ranking the most capable AI systems. Yet, in this work we identify systematic issues that have resulted in a distorted playing field. We find that undisclosed private testing practices benefit a handful of providers who are able to test multiple variants before public release and retract scores if desired. We establish that the ability of these providers to choose the best score leads to biased Arena scores due to selective disclosure of performance results. At an extreme, we identify 27 private LLM variants tested by Meta in the lead-up to the Llama-4 release. We also establish that proprietary closed models are sampled at higher rates (number of battles) and have fewer models removed from the arena than open-weight and open-source alternatives. Both these policies lead to large data access asymmetries over time. Providers like Google and OpenAI have received an estimated 19.2% and 20.4% of all data on the arena, respectively. In contrast, a combined 83 open-weight models have only received an estimated 29.7% of the total data. We show that access to Chatbot Arena data yields substantial benefits; even limited additional data can result in relative performance gains of up to 112% on the arena distribution, based on our conservative estimates. Together, these dynamics result in overfitting to Arena-specific dynamics rather than general model quality. The Arena builds on the substantial efforts of both the organizers and an open community that maintains this valuable evaluation platform. We offer actionable recommendations to reform the Chatbot Arena's evaluation framework and promote fairer, more transparent benchmarking for the field

  • 13 authors
·
Apr 29, 2025 3

OpenCoder: The Open Cookbook for Top-Tier Code Large Language Models

Large language models (LLMs) for code have become indispensable in various domains, including code generation, reasoning tasks and agent systems.While open-access code LLMs are increasingly approaching the performance levels of proprietary models, high-quality code LLMs suitable for rigorous scientific investigation, particularly those with reproducible data processing pipelines and transparent training protocols, remain limited. The scarcity is due to various challenges, including resource constraints, ethical considerations, and the competitive advantages of keeping models advanced. To address the gap, we introduce OpenCoder, a top-tier code LLM that not only achieves performance comparable to leading models but also serves as an ``open cookbook'' for the research community. Unlike most prior efforts, we release not only model weights and inference code, but also the reproducible training data, complete data processing pipeline, rigorous experimental ablation results, and detailed training protocols for open scientific research. Through this comprehensive release, we identify the key ingredients for building a top-tier code LLM: (1) code optimized heuristic rules for data cleaning and methods for data deduplication, (2) recall of text corpus related to code and (3) high-quality synthetic data in both annealing and supervised fine-tuning stages. By offering this level of openness, we aim to broaden access to all aspects of a top-tier code LLM, with OpenCoder serving as both a powerful model and an open foundation to accelerate research, and enable reproducible advancements in code AI.

  • 19 authors
·
Nov 7, 2024 6

Orthogonal Boundary Unlearning for Dual-Use Concepts in Large Language Models

Mitigating catastrophic risks from large language models requires excising hazardous operational capabilities, such as cyberwarfare exploitation and pathogen enhancement, without degrading benign scientific utility. In these dual-use domains, legitimate defensive science and malicious attacks share vocabulary, syntax, and internal model representations, causing standard unlearning methods to induce severe collateral damage (concept bleeding). In this work, we present Orthogonal Boundary Unlearning (OBU), a mathematically grounded framework designed to eliminate collateral damage on benign dual-use capabilities. OBU extracts a domain-matched capability subspace from paired calibration queries via singular value decomposition on empirical activation covariances, and restricts parameter updates strictly to the orthogonal null space. This guarantees that benign representations experience zero parameter perturbation along the spanned calibration subspace. We present two complementary realizations of OBU: Projected LoRA, which applies the orthogonal constraint during iterative gradient-based fine-tuning, and Closed-Form Weight Surgery, which directly edits model weights in a single analytical step without training. Across four modern open-weight foundation models (Gemma-3-4B, Qwen3.5-4B, SmolLM3-3B, and Granite-4.2-3B), OBU achieves strong dual-use concept separation, substantially mitigates in-context priming attacks, and demonstrates durable resistance against adversarial relearning without degrading benign domain competence.

  • 1 authors
·
Oct 19

MatchMiner-AI: An Open-Source Solution for Cancer Clinical Trial Matching

Clinical trials drive improvements in cancer treatments and outcomes. However, most adults with cancer do not participate in trials, and trials often fail to enroll enough patients to answer their scientific questions. Artificial intelligence could accelerate matching of patients to appropriate clinical trials. Here, we describe the development and evaluation of the MatchMiner-AI pipeline for clinical trial searching and ranking. MatchMiner-AI focuses on matching patients to potential trials based on core criteria describing clinical "spaces," or disease contexts, targeted by a trial. It aims to accelerate the human work of identifying potential matches, not to fully automate trial screening. The pipeline includes modules for extraction of key information from a patient's longitudinal electronic health record; rapid ranking of candidate trial-patient matches based on embeddings in vector space; and classification of whether a candidate match represents a reasonable clinical consideration. Code and synthetic data are available at https://huggingface.co/ksg-dfci/MatchMiner-AI . Model weights based on synthetic data are available at https://huggingface.co/ksg-dfci/TrialSpace and https://huggingface.co/ksg-dfci/TrialChecker . A simple cancer clinical trial search engine to demonstrate pipeline components is available at https://huggingface.co/spaces/ksg-dfci/trial_search_alpha .

  • 14 authors
·
Dec 22, 2024

MuQ-Eval: An Open-Source Per-Sample Quality Metric for AI Music Generation Evaluation

Distributional metrics such as Fréchet Audio Distance cannot score individual music clips and correlate poorly with human judgments, while the only per-sample learned metric achieving high human correlation is closed-source. We introduce MUQ-EVAL, an open-source per-sample quality metric for AIgenerated music built by training lightweight prediction heads on frozen MuQ-310M features using MusicEval, a dataset of generated clips from 31 text-to-music systems with expert quality ratings. Our simplest model, frozen features with attention pooling and a two-layer MLP, achieves system-level SRCC = 0.957 and utterance-level SRCC = 0.838 with human mean opinion scores. A systematic ablation over training objectives and adaptation strategies shows that no addition meaningfully improves the frozen baseline, indicating that frozen MuQ representations already capture quality-relevant information. Encoder choice is the dominant design factor, outweighing all architectural and training decisions. LoRA-adapted models trained on as few as 150 clips already achieve usable correlation, enabling personalized quality evaluators from individual listener annotations. A controlled degradation analysis reveals selective sensitivity to signal-level artifacts but insensitivity to musical-structural distortions. Our metric, MUQ-EVAL, is fully open-source, outperforms existing open per-sample metrics, and runs in real time on a single consumer GPU. Code, model weights, and evaluation scripts are available at https://github.com/dgtql/MuQ-Eval.

  • 2 authors
·
Mar 23

Generalizing Manipulation Skills with a Local Coding Agent

Today, progress in open-weight language models enables systems capable of writing, executing and debugging code while still running on a single workstation. Most language-driven robots give the model a fixed action interface or a trained policy. Generalizing to a new task therefore means more engineering effort or more data collection, both time-consuming. We investigate whether a local open-weight vision-language model can control a robot and one-shot generalize to new variations of a task without new human programming or training. We let a local open-weight VLM, Qwen3.8-27B, drive a UR3e robotic arm from a coding-agent harness. It writes and runs its own code above a service that implements kinematics, safety limits and classic computer vision techniques. We investigate if this system is capable of generalizing to unseen tasks. Specifically, we test it on nine tasks built from children's toys designed to probe generalization capability across various object characteristics: color, size, shape, and task variation of those. With five trials for each task, we observe generalization in 30 out of 45 trials with durations ranging from 3.4 to 67.5 minutes depending on task complexity. We further test if there is a speedup when an agent is asked to redo the task after successful completion. This resulted in a 50% reduction in duration, indicating that there is self-improvement over time. Finally, we expose the limitations of a local coding agent. We believe that solving those limitations combined with further investigation of self-improvement over time points at a direct path toward real-world deployment of a local coding agent.

  • 4 authors
·
Sep 21

HiDream-I1: A High-Efficient Image Generative Foundation Model with Sparse Diffusion Transformer

Recent advancements in image generative foundation models have prioritized quality improvements but often at the cost of increased computational complexity and inference latency. To address this critical trade-off, we introduce HiDream-I1, a new open-source image generative foundation model with 17B parameters that achieves state-of-the-art image generation quality within seconds. HiDream-I1 is constructed with a new sparse Diffusion Transformer (DiT) structure. Specifically, it starts with a dual-stream decoupled design of sparse DiT with dynamic Mixture-of-Experts (MoE) architecture, in which two separate encoders are first involved to independently process image and text tokens. Then, a single-stream sparse DiT structure with dynamic MoE architecture is adopted to trigger multi-model interaction for image generation in a cost-efficient manner. To support flexiable accessibility with varied model capabilities, we provide HiDream-I1 in three variants: HiDream-I1-Full, HiDream-I1-Dev, and HiDream-I1-Fast. Furthermore, we go beyond the typical text-to-image generation and remould HiDream-I1 with additional image conditions to perform precise, instruction-based editing on given images, yielding a new instruction-based image editing model namely HiDream-E1. Ultimately, by integrating text-to-image generation and instruction-based image editing, HiDream-I1 evolves to form a comprehensive image agent (HiDream-A1) capable of fully interactive image creation and refinement. To accelerate multi-modal AIGC research, we have open-sourced all the codes and model weights of HiDream-I1-Full, HiDream-I1-Dev, HiDream-I1-Fast, HiDream-E1 through our project websites: https://github.com/HiDream-ai/HiDream-I1 and https://github.com/HiDream-ai/HiDream-E1. All features can be directly experienced via https://vivago.ai/studio.

  • 22 authors
·
May 28, 2025

Apriel-Reasoner: RL Post-Training for General-Purpose and Efficient Reasoning

Building general-purpose reasoning models using reinforcement learning with verifiable rewards (RLVR) across diverse domains has been widely adopted by frontier open-weight models. However, their training recipes and domain mixtures are often not disclosed. Joint optimization across domains poses significant challenges: domains vary widely in rollout length, problem difficulty and sample efficiency. Further, models with long chain-of-thought traces increase inference cost and latency, making efficiency critical for practical deployment. We present Apriel-Reasoner, trained with a fully reproducible multi-domain RL post-training recipe on Apriel-Base, a 15B-parameter open-weight LLM, across five domains using public datasets: mathematics, code generation, instruction following, logical puzzles and function calling. We introduce an adaptive domain sampling mechanism that preserves target domain ratios despite heterogeneous rollout dynamics, and a difficulty-aware extension of the standard length penalty that, with no additional training overhead, encourages longer reasoning for difficult problems and shorter traces for easy ones. Trained with a strict 16K-token output budget, Apriel-Reasoner generalizes to 32K tokens at inference and improves over Apriel-Base on AIME 2025, GPQA, MMLU-Pro, and LiveCodeBench while producing 30-50% shorter reasoning traces. It matches strong open-weight models of similar size at lower token cost, thereby pushing the Pareto frontier of accuracy versus token budget.

ServiceNow ServiceNow
·
Apr 1 1

HouseholdBench: Evaluating Large Language Models as Predictors of Household Economic Behavior

Large language models (LLMs) have the potential to meet a key goal in economics: a quantitative model of household decision making, across a variety of settings. Yet existing evaluations cover few surveys and outcomes, and do not study how households adjust to changing economic conditions. We introduce a new evaluation, HouseholdBench, which unites 6 U.S. household surveys and 32 prediction tasks spanning numeric, categorical and probabilistic outcomes, related to consumption, income, labor, expectations, and housing. Using past behavior, demographics and macroeconomic conditions, the tasks test whether LLMs predict behavior, including how households adjust to changes in various policies. We evaluate 13 proprietary and open-weight LLMs against a no-change baseline and a gradient-boosted tree model. Most LLMs outperform the no-change baseline, including for policy response tasks -- with the best model lowering error for numeric outcomes by 12.2%. Across most tasks, gradient-boosted trees rank first; leading proprietary LLMs approach their performance, but open-weight models lag. LLMs exhibit systematic over- and underprediction across different tasks. We identify methods that enable a 4 billion parameter open-weight model to match proprietary models' performance: fine-tuning and aggregating 16 predictions per observation. Improvements generalize to policy-response tasks, which are excluded from fine-tuning. We release our datasets, code, and leaderboard on our website: https://jn-huang.github.io/householdbench

  • 7 authors
·
Oct 5

Bongard: Training Machine Intuition

Human intelligence relies heavily on learned intuition: recognising patterns and judging situations without explicitly unfolding every intermediate step. We introduce Bongard, an open-weight System One model that treats machine intuition as an independent capability to design and train. A T5Gemma 2 4B-4B encoder-decoder separates reading the evidence from making judgments. The encoder reads the state bidirectionally together with the question instructions, and separate decoder branches share this encoding, so many judgments about the same situation require only one reading of the state. A trained head returns probabilities over the supplied candidates without generating text. Training proceeds in three stages, from supervised judgments to semantic relationships to action outcomes, and each stage updates all 7.09 billion trainable parameters on one Blackwell GPU. Joint-embedding post-training raises accuracy on held-out rephrasings from 75.7% to 85.9%. A sandbox stage then learns outcome distributions from action rollouts and exact oracles, raising accuracy on a frozen sandbox panel from 50.6% to 64.8%. On DecisionBench, the final model reaches 78.05% accuracy over 23,900 decisions and ranks fourth of 61 systems in the public comparison. On one RTX PRO 6000, its median latency is 36 ms for short requests, and 32 questions about one state take 221 ms. Bongard demonstrates that machine intuition can be systematically trained via representation learning and outcome feedback, providing an open, efficient alternative for high-throughput decision workloads.

  • 3 authors
·
Sep 29

ZGCM-1: A Fully Open and Extremely Efficient Foundation Model for Math and Agentic Search

In this work, we present ZGCM-1, a fully open 7B dense foundation model trained from scratch with extreme data, system, and algorithmic efficiency. ZGCM-1 is founded on a core premise: compact models cannot passively memorize the open web, but can overcome parametric capacity limits by coupling deliberate internal thinking with active external tool use. To support this paradigm across a 256K context, we develop an end-to-end, high-efficiency open training recipe: Architecture & System Co-design: interleaved gated sliding-window and full attention, and a stable FP8 Muon optimizer; Progressive Curriculum & MDP Mid-Training: context scaling across 16K, 64K, and 256K, and the reformulation of interaction traces into Markov Decision Processes. Furthermore, we establish an AI-native R&D workflow where agent swarms autonomously manage cluster operations, data curation, and rapid diagnostic evaluation. Extensive evaluations show that ZGCM-1-7B is competitive across 7B model family on general benchmarks. On several challenging mathematical reasoning and agentic search suites, it remains competitive with frontier models orders of magnitude larger, such as Qwen3-235B-A22B and GLM-5.1. We also show that our pre-training design offers a ~4.2x efficiency improvement in 16K pre-training time-to-loss. Across the full development lifecycle, we distill eight actionable empirical findings-spanning architectural scaling, SFT quality pruning, long-context generalization, and agentic co-training dynamics. To facilitate community research, we open-source model weights from the pre-training, mid-training, and post-training stages, intermediate checkpoints, training code, per-stage data and data recipes, and W&B logs.

zgcagi ZGCAGI
·
Sep 10 8

MedS^3: Towards Medical Small Language Models with Self-Evolved Slow Thinking

Medical language models (MLMs) have become pivotal in advancing medical natural language processing. However, prior models that rely on pre-training or supervised fine-tuning often exhibit low data efficiency and limited practicality in real-world clinical applications. While OpenAIs O1 highlights test-time scaling in mathematics, attempts to replicate this approach in medicine typically distill responses from GPT-series models to open-source models, focusing primarily on multiple-choice tasks. This strategy, though straightforward, neglects critical concerns like data privacy and realistic deployment in clinical settings. In this work, we present a deployable, small-scale medical language model, \mone, designed for long-chain reasoning in clinical tasks using a self-evolution paradigm. Starting with a seed dataset of around 8,000 instances spanning five domains and 16 datasets, we prompt a base policy model to perform Monte Carlo Tree Search (MCTS) to construct verifiable reasoning chains. Each reasoning step is assigned an evolution rollout value, allowing verified trajectories to train the policy model and the reward model. During inference, the policy model generates multiple responses, and the reward model selects the one with the highest reward score. Experiments on eleven evaluation datasets demonstrate that \mone outperforms prior open-source models by 2 points, with the addition of the reward model further boosting performance (sim13 points), surpassing GPT-4o-mini. Code and data are available at https://github.com/pixas/MedSSS.

  • 6 authors
·
Jan 21, 2025

OpenELM: An Efficient Language Model Family with Open-source Training and Inference Framework

The reproducibility and transparency of large language models are crucial for advancing open research, ensuring the trustworthiness of results, and enabling investigations into data and model biases, as well as potential risks. To this end, we release OpenELM, a state-of-the-art open language model. OpenELM uses a layer-wise scaling strategy to efficiently allocate parameters within each layer of the transformer model, leading to enhanced accuracy. For example, with a parameter budget of approximately one billion parameters, OpenELM exhibits a 2.36% improvement in accuracy compared to OLMo while requiring 2times fewer pre-training tokens. Diverging from prior practices that only provide model weights and inference code, and pre-train on private datasets, our release includes the complete framework for training and evaluation of the language model on publicly available datasets, including training logs, multiple checkpoints, and pre-training configurations. We also release code to convert models to MLX library for inference and fine-tuning on Apple devices. This comprehensive release aims to empower and strengthen the open research community, paving the way for future open research endeavors. Our source code along with pre-trained model weights and training recipes is available at https://github.com/apple/corenet. Additionally, \model models can be found on HuggingFace at: https://huggingface.co/apple/OpenELM.

  • 11 authors
·
Apr 22, 2024 14

Fully Open Source Moxin-7B Technical Report

Recently, Large Language Models (LLMs) have undergone a significant transformation, marked by a rapid rise in both their popularity and capabilities. Leading this evolution are proprietary LLMs like GPT-4 and GPT-o1, which have captured widespread attention in the AI community due to their remarkable performance and versatility. Simultaneously, open-source LLMs, such as LLaMA and Mistral, have made great contributions to the ever-increasing popularity of LLMs due to the ease to customize and deploy the models across diverse applications. Although open-source LLMs present unprecedented opportunities for innovation and research, the commercialization of LLMs has raised concerns about transparency, reproducibility, and safety. Many open-source LLMs fail to meet fundamental transparency requirements by withholding essential components like training code and data, and some use restrictive licenses whilst claiming to be "open-source," which may hinder further innovations on LLMs. To mitigate this issue, we introduce Moxin 7B, a fully open-source LLM developed in accordance with the Model Openness Framework (MOF), a ranked classification system that evaluates AI models based on model completeness and openness, adhering to principles of open science, open source, open data, and open access. Our model achieves the highest MOF classification level of "open science" through the comprehensive release of pre-training code and configurations, training and fine-tuning datasets, and intermediate and final checkpoints. Experiments show that our model achieves superior performance in zero-shot evaluation compared with popular 7B models and performs competitively in few-shot evaluation.

  • 16 authors
·
Dec 7, 2024 2

Model Breadcrumbs: Scaling Multi-Task Model Merging with Sparse Masks

The rapid development of AI systems has been greatly influenced by the emergence of foundation models. A common approach for targeted problems involves fine-tuning these pre-trained foundation models for specific target tasks, resulting in a rapid spread of models fine-tuned across a diverse array of tasks. This work focuses on the problem of merging multiple fine-tunings of the same foundation model derived from a spectrum of auxiliary tasks. We introduce a new simple method, Model Breadcrumbs, which consists of a sparsely defined set of weights that carve out a trajectory within the weight space of a pre-trained model, enhancing task performance when traversed. These breadcrumbs are constructed by subtracting the weights from a pre-trained model before and after fine-tuning, followed by a sparsification process that eliminates weight outliers and negligible perturbations. Our experiments demonstrate the effectiveness of Model Breadcrumbs to simultaneously improve performance across multiple tasks. This contribution aligns with the evolving paradigm of updatable machine learning, reminiscent of the collaborative principles underlying open-source software development, fostering a community-driven effort to reliably update machine learning models. Our method is shown to be more efficient and unlike previous proposals does not require hyperparameter tuning for each new task added. Through extensive experimentation involving various models, tasks, and modalities we establish that integrating Model Breadcrumbs offers a simple, efficient, and highly effective approach for constructing multi-task models and facilitating updates to foundation models.

  • 2 authors
·
Dec 11, 2023

Skywork R1V2: Multimodal Hybrid Reinforcement Learning for Reasoning

We present Skywork R1V2, a next-generation multimodal reasoning model and a major leap forward from its predecessor, Skywork R1V. At its core, R1V2 introduces a hybrid reinforcement learning paradigm that harmonizes reward-model guidance with rule-based strategies, thereby addressing the long-standing challenge of balancing sophisticated reasoning capabilities with broad generalization. To further enhance training efficiency, we propose the Selective Sample Buffer (SSB) mechanism, which effectively counters the ``Vanishing Advantages'' dilemma inherent in Group Relative Policy Optimization (GRPO) by prioritizing high-value samples throughout the optimization process. Notably, we observe that excessive reinforcement signals can induce visual hallucinations--a phenomenon we systematically monitor and mitigate through calibrated reward thresholds throughout the training process. Empirical results affirm the exceptional capability of R1V2, with benchmark-leading performances such as 62.6 on OlympiadBench, 79.0 on AIME2024, 63.6 on LiveCodeBench, and 74.0 on MMMU. These results underscore R1V2's superiority over existing open-source models and demonstrate significant progress in closing the performance gap with premier proprietary systems, including Gemini 2.5 and OpenAI o4-mini. The Skywork R1V2 model weights have been publicly released to promote openness and reproducibility https://huggingface.co/Skywork/Skywork-R1V2-38B.

Skywork Skywork
·
Apr 23, 2025 2

Jailbreaking Open-Weight LLMs via Random Embedding Perturbations

While open-weight models have enjoyed steady progress in capabilities and wide adoption across multiple domains, their safety remains an important concern. One key feature is the ability to refuse or deflect harmful, malicious, or insensitive prompts. In this paper, we expose safety vulnerabilities across six common open-weight LLMs of various sizes that consistently lead to harmful or unsafe responses on the JailbreakBench benchmark dataset. Our proposed attack, Perturbed Embedding Vector (PEV), is a simple and fast "jailbreaking" technique that is cheaper than prior approaches, which typically require gradient computations, per-prompt optimizations, or altering internal weights of the models. PEV just adds independent Gaussian noise in the embedding vector representations of the prompt, with no need for further manipulations. To generate unsafe responses, we repeatedly sample additive noise from this distribution. In our experiments, we observe that the average compute cost to get the first successful attack is up to an order of magnitude less than previous attacks. The first successful jailbreak on a new prompt typically arrives within one minute on every tested model, and PEV generates unsafe responses across all models for all prompts in JailbreakBench. No other tested method achieves such results, despite them taking longer to run. More broadly, we believe that understanding the behavior of LLMs under perturbations in the embedding vectors is an important research direction: while perturbations constitute a major security risk, they can also serve as a valuable tool for exploring the dynamical behavior of such models.

  • 4 authors
·
Oct 4

2 OLMo 2 Furious

We present OLMo 2, the next generation of our fully open language models. OLMo 2 includes dense autoregressive models with improved architecture and training recipe, pretraining data mixtures, and instruction tuning recipes. Our modified model architecture and training recipe achieve both better training stability and improved per-token efficiency. Our updated pretraining data mixture introduces a new, specialized data mix called Dolmino Mix 1124, which significantly improves model capabilities across many downstream task benchmarks when introduced via late-stage curriculum training (i.e. specialized data during the annealing phase of pretraining). Finally, we incorporate best practices from T\"ulu 3 to develop OLMo 2-Instruct, focusing on permissive data and extending our final-stage reinforcement learning with verifiable rewards (RLVR). Our OLMo 2 base models sit at the Pareto frontier of performance to compute, often matching or outperforming open-weight only models like Llama 3.1 and Qwen 2.5 while using fewer FLOPs and with fully transparent training data, code, and recipe. Our fully open OLMo 2-Instruct models are competitive with or surpassing open-weight only models of comparable size, including Qwen 2.5, Llama 3.1 and Gemma 2. We release all OLMo 2 artifacts openly -- models at 7B and 13B scales, both pretrained and post-trained, including their full training data, training code and recipes, training logs and thousands of intermediate checkpoints. The final instruction model is available on the Ai2 Playground as a free research demo.

  • 40 authors
·
Dec 31, 2024

OpenAGI: When LLM Meets Domain Experts

Human intelligence excels at combining basic skills to solve complex tasks. This capability is vital for Artificial Intelligence (AI) and should be embedded in comprehensive intelligent models, enabling them to harness expert models for complex task-solving towards Artificial General Intelligence (AGI). Large Language Models (LLMs) show promising learning and reasoning abilities, and can effectively use external models, tools or APIs to tackle complex problems. In this work, we introduce OpenAGI, an open-source AGI research platform designed for multi-step, real-world tasks. Specifically, OpenAGI uses a dual strategy, integrating standard benchmark tasks for benchmarking and evaluation, and open-ended tasks including more expandable models, tools or APIs for creative problem-solving. Tasks are presented as natural language queries to the LLM, which then selects and executes appropriate models. We also propose a Reinforcement Learning from Task Feedback (RLTF) mechanism that uses task results to improve the LLM's ability, which creates a self-improving AI feedback loop. While we acknowledge that AGI is a broad and multifaceted research challenge with no singularly defined solution path, the integration of LLMs with domain-specific expert models, inspired by mirroring the blend of general and specialized intelligence in humans, offers a promising approach towards AGI. We are open-sourcing the OpenAGI project's code, dataset, benchmarks, evaluation methods, and demo to foster community involvement in AGI advancement: https://github.com/agiresearch/OpenAGI.

  • 8 authors
·
Apr 9, 2023

Towards Open Set Deep Networks

Deep networks have produced significant gains for various visual recognition problems, leading to high impact academic and commercial applications. Recent work in deep networks highlighted that it is easy to generate images that humans would never classify as a particular object class, yet networks classify such images high confidence as that given class - deep network are easily fooled with images humans do not consider meaningful. The closed set nature of deep networks forces them to choose from one of the known classes leading to such artifacts. Recognition in the real world is open set, i.e. the recognition system should reject unknown/unseen classes at test time. We present a methodology to adapt deep networks for open set recognition, by introducing a new model layer, OpenMax, which estimates the probability of an input being from an unknown class. A key element of estimating the unknown probability is adapting Meta-Recognition concepts to the activation patterns in the penultimate layer of the network. OpenMax allows rejection of "fooling" and unrelated open set images presented to the system; OpenMax greatly reduces the number of obvious errors made by a deep network. We prove that the OpenMax concept provides bounded open space risk, thereby formally providing an open set recognition solution. We evaluate the resulting open set deep networks using pre-trained networks from the Caffe Model-zoo on ImageNet 2012 validation data, and thousands of fooling and open set images. The proposed OpenMax model significantly outperforms open set recognition accuracy of basic deep networks as well as deep networks with thresholding of SoftMax probabilities.

  • 2 authors
·
Nov 18, 2015

Releasing the Inner Jev: A Simple Recipe for Open Decision Models

LLM-based decision-making systems, also called System One models, have recently gained popularity, most notably through Jev (Almeida, 2026). Given a typed input state, a question, and a set of options, they return a probability for each option in a single forward pass, without text generation. We show that existing open instruction-tuned language models can achieve comparable performance without any additional training, by reading out answers from letters (A, B, C, etc.) in the model's output logits at the last token position. Furthermore, we show how a simple supervised fine-tuning recipe can improve their performance further. We evaluate four open instruction-tuned language models: Gemma 4 31B, Gemma 4 12B, Qwen3.6-27B, and Qwen3.5-4B. We fine-tune each using LoRA and a decision head initialized from a slice of the language model head. Furthermore, we introduce OpenDecisions, a novel 2,352-question validation dataset designed to reflect the task composition of JevBench (JevBench main- tainers, 2026) and which computes a Capability score based on accuracy and calibration metrics. Without fine-tuning, Gemma 4 31B scores 79.6 on OpenDecisions, compared to Jev's 80.1. After undergoing our fine-tuning recipe, it scores 84.4 on OpenDecisions and 81.5 on JevBench v1.7, outperforming Jev by 4.3 and 4.4 Capability points respectively and setting a new state-of-the-art on OpenDecisions. On a suite of public decision datasets, our models achieve accuracy comparable to Jev, with lower calibration error. Our results show that open language models already possess System One capabilities, and with simple fine-tuning they outperform Jev on a wide range of decision tasks. We release our models, serving code, and OpenDecisions.

  • 3 authors
·
Oct 11 2

K2-Horizon: A Frontier Fleet of Open Source Language Models

We present K2-Horizon, a fleet of six fully open language models, from a 0.9B dense model to a 375B-A23B MoE, built for general-purpose reasoning and agentic work across math and science, software engineering, deep research, office automation, and beyond. The models lead or are competitive with strong open models of their size on agentic and coding benchmarks. On the modeling side, to strengthen reasoning, we introduce Mixture-of-Value Attention (MoVA), applying MoE to attention value projections, and softplus attention gating, a more flexible, theoretically motivated gate. Our 36B-A4B model uses both and nearly matches a 32B dense model trained on the same data, with one-seventh the active parameters. We also introduce Uno, lossless diffusion adapters that speed up decoding by up to 2.2x without a separate draft model. Our release follows the LLM360 definition of open source for transparency and reproducibility: the full development history, including intermediate checkpoints from every training stage, pre-training data, training logs, and all training, evaluation, and infrastructure code, notably our production-scale xLLM framework for dense and MoE training and the RL360 reinforcement-learning stack. Beyond the data itself, we release and document in detail every pipeline that built it, the part of model development that open releases most rarely disclose. These pipelines produced roughly 10T synthetic pre-training tokens, showing that synthetic data can be a major ingredient of pre-training at scale. Four of the models share one 22T-token pre-training corpus and recipe, revealing consistent scaling behavior and enabling controlled studies of scale and sparsity. All artifacts are available at https://ifm.ai/k2/

AstroMLab 1: Who Wins Astronomy Jeopardy!?

We present a comprehensive evaluation of proprietary and open-weights large language models using the first astronomy-specific benchmarking dataset. This dataset comprises 4,425 multiple-choice questions curated from the Annual Review of Astronomy and Astrophysics, covering a broad range of astrophysical topics. Our analysis examines model performance across various astronomical subfields and assesses response calibration, crucial for potential deployment in research environments. Claude-3.5-Sonnet outperforms competitors by up to 4.6 percentage points, achieving 85.0% accuracy. For proprietary models, we observed a universal reduction in cost every 3-to-12 months to achieve similar score in this particular astronomy benchmark. Open-source models have rapidly improved, with LLaMA-3-70b (80.6%) and Qwen-2-72b (77.7%) now competing with some of the best proprietary models. We identify performance variations across topics, with non-English-focused models generally struggling more in exoplanet-related fields, stellar astrophysics, and instrumentation related questions. These challenges likely stem from less abundant training data, limited historical context, and rapid recent developments in these areas. This pattern is observed across both open-weights and proprietary models, with regional dependencies evident, highlighting the impact of training data diversity on model performance in specialized scientific domains. Top-performing models demonstrate well-calibrated confidence, with correlations above 0.9 between confidence and correctness, though they tend to be slightly underconfident. The development for fast, low-cost inference of open-weights models presents new opportunities for affordable deployment in astronomy. The rapid progress observed suggests that LLM-driven research in astronomy may become feasible in the near future.

  • 11 authors
·
Jul 15, 2024